HydroX AI at ICLR-HAIC 2025: Pioneering Safer and Smarter Language Generation
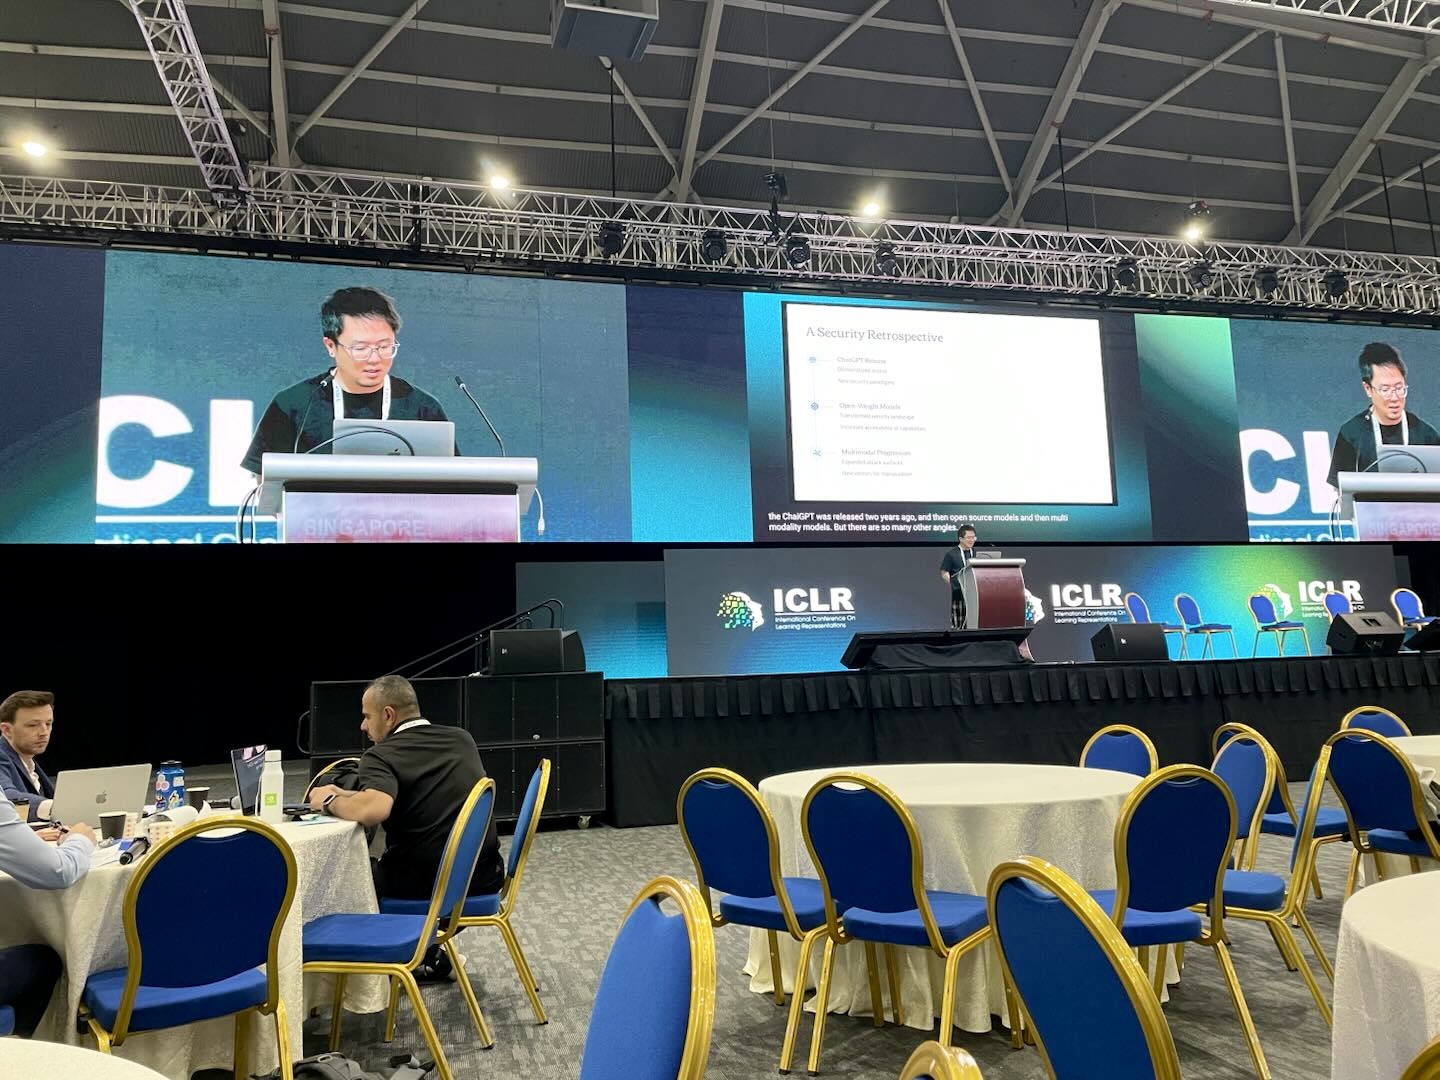
We’re excited to share key highlights from our recent talk at the ICLR 2025 Workshop on Human-AI Coevolution (HAIC) in Singapore.

We’re excited to share key highlights from our recent talk at the ICLR 2025 Workshop on Human-AI Coevolution (HAIC) in Singapore, where HydroX AI presented cutting-edge research on optimizing safe and aligned language generation.
Our session, “Optimizing Safe and Aligned Language Generation: A Multi-Objective GRPO Approach,” sparked insightful discussions on how to build large language models (LLMs) that are not only more intelligent — but also safer, more interpretable, and computationally efficient.
🔍 Key Findings from Our Research
1. Higher Alignment Across Multiple Objectives
Using our GRPO-based approach, we fine-tuned models of various sizes (0.5B, 7B, 14B) and achieved significant gains in safety, truthfulness, and overall response quality.
GRPO-trained models showed improved refusal rates on unsafe prompts — without compromising helpfulness or coherence. This represents a major step forward in balancing model alignment with usability.
2. Lower Computational Cost Compared to RLHF
Unlike traditional RLHF, GRPO eliminates the need for a separate value critic, resulting in greater training stability, reduced computational overhead, and simplified implementation.
This makes robust alignment more accessible, particularly for organizations with limited compute resources.
3. More Interpretability and Control
GRPO preserves distinct reward signals — such as safety, politeness, and factuality — enabling dynamic rebalancing of alignment objectives, fine-grained interpretability, and no full retraining required to adjust model behavior.